So, multiple times now I have found myself helping out people making audio visualizers. It’s mostly easy but being able to bang out one that looks good takes a certain amount of tacit knowledge. The values you get from an FFT are linear in frequency and in magnitude, and noisy. To make a visualizer that looks good you need to sort out all three. My target audience for this post is people who have dealt with these but were never quite sure they understood what was going on.
Since this is about fundamentals, this post is only covers how to go from FFT frequency amplitiudes to the simplest spectrum analyzer you can make: monochrome bars, each bar gets a frequency, they move up and down. I’m not going to get into the FFT itself or justify any basic facts about it. Maybe later.
First order of business for this page is to fix the garbage the WebAudio AudioAnalyser node gives you. This means calling it like this:
analyser.fftSize = FFTSize;
analyser.smoothingTimeConstant = 0;
analyser.minDecibels = -100;
analyser.maxDecibels = 0;
and undecibeling it when it comes out the other end to get linear DFT magnitudes with no smoothing (do not use the WebAudio smoothing). Now we can start.
Problem: noisy
Right, WebAudio gives you smoothingTimeConstant and I claim this is bad. This is simple, it’s not frame rate independent. This is the display frame rate and has nothing do with the FFT size or audio sample rate. To make it independent, compute the smoothing constant with your time delta:
where is the decay half-life. You can convince yourself this is plausibly right by knowing beforehand that the way this has to work is if you feed in a single then s at intervals of with , then it should fall by half immediately, and yes, . You then also check that stepping twice as fast gives after two time steps, and yea, , and a step of then works, too. You also know that this is pretty convincing because the quantity we care about is the ratio and not the actual numbers involved.
But if you do only this, it’s sloshy. If you stare at tuneform you’ll see it there, too. There doesn’t seem to be a middle ground between jittery and smooth that doesn’t add inertia.
The trick for this is to modulate depending on how the sound is changing, updating for every bar and every frame. Make it speed it up to follow attacks and slow it down to smooth out steady-state noise. Once you know you can do this it’s pretty easy to hack something together.
If you don’t want to hack, try this. The rest of this post isn’t going to be quite so hardcore. Define
The idea is that will kick in when the delta between and is small enough. Compute a per-bar with
When this breaks, set in that case. Then apply the usual filter step
And that’s it. By the way, the discovery fiction version of this begins “Boy, I sure would like to multiply H by an term”, which mostly works but is fiddly and annoying to tune; is then a nicer curve than an and is a way to tune it. This filter has 3 regimes:
How it does that is going to take a little unpacking. All we’re doing is updating the half-life for a bar, so we just need to understand how it’s computing .
First, is a normalized delta from the previous frame, normalized with respect to itself. This normalization makes a lot of the fiddly parameterization you typically have with this kind of thing go away. You can think of it like an approximation to . That thing is called the logarithmic derivative, which is a hint that this thing is responding to amplitude ratios rather than differences. This is nice because it keeps the filter scale invariant; that is, you get the same filtering before and after applying gain (I should check this).
If you want to understand , stick it in desmos. Ignore for a moment and assume its value is . You’ll find that is an term that makes us respond faster to new, loud sound, and is a flipped gaussian, to lengthen the effective half-life when is small. This smooths more agressively when the bar heights are jittery rather than moving.
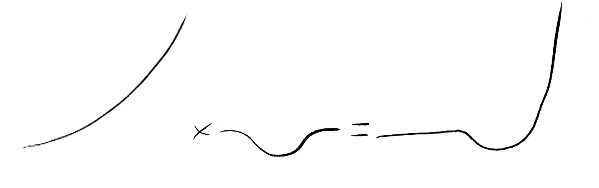
Importantly, both of these terms go to as goes to , so when we have and recover as our decay time.
Finally, . This gives us a way to tune the adaptivity. Without it, frame deltas near zero lock bars in place, because we’ve otherwise explicitly designed zero delta to give . Setting to a value in lifts the floor of the gaussian preventing this from happening. But how to choose a value for ? Well, we know is going to scale , and is going to fix the minimum value can take on. So define as the half-life when and then is whatever gives in that case.
This is an example of an adaptive filter in the same vein as the 1€ Filter. Before writing this post I had something a little more adhoc here that was annoying to parameterize. I landed on this after cleaning it up. If you look at 1€, they have this whole process by which you pick good parameters for it. I want to avoid that. You can introduce terms to the exponentials if you want more control over the filter here; once you understand the shape of the curve you are manipulating it’s pretty clear what is going on. The normalisation and asymmetry means this thing is only really appropriate for positive-only signals, in this respect it’s unlike 1€ where you can slam it on position data.
Problem: linear in frequency
Linear FFT bins to logarithmic bars. This is explained everywhere but I feel like a couple fundamental pieces get dropped pretty often. The first is that underneath the logarithms that map bin frequencies to bar frequencies there’s a simple lerp/unlerp logic and the second is how to actually think about mapping values at those frequencies into bars.
float lerp(float a, float b, float t) {
    return (1.0f - t)*a + t*b;
}

float unlerp(float a, float b, float x) {
    return (x - a) / (b - a);
}

float remap(float a0, float a1, float b0, float b1, float x) {
    return lerp(b0, b1, unlerp(a0, a1, x));
}
Now remap maps the entire range to by applying a scale and shift. How do we use this? We want bars that equally subdivide octaves. We have bins and a desired frequency range. To equally subdivide octaves, which double in frequency per octave, we want our bar frequencies to take linear steps after applying . So construct that directly with remap:
float bar_to_frequency(float b, int32_t B, float f0, float f1) {
    float f_log = remap(0.0f, float(B), log2f(f0), log2f(f1), b);
    return powf(2.0f, f_log);
}

float frequency_to_bin(float f, int32_t N, float sample_rate) {
    float nyquist = sample_rate / 2.0f;
    return remap(0.0f, nyquist, 0.0f, float(N), f);
}
And we’re done. It’s maybe worth noting that the things we care about are the endpoints and the logarithmic warp, and the endpoints make the choice of base irrelevant; we could have used expf and logf.
This looks a little different from how people usually do this. Yes. It’ll appear if you expand it out and simplify.
Next, resampling bins into bars. First thing to understand here is that we do this by reaching back from the output, bars, to the input, bins, to grab what we need for each bar. That is, at no point do we ever pick up a bin, ask its frequency, and try to locate the corresponding bar for that frequency. At low frequencies, this will leave gaps: there’ll be so little frequency resolution in the low bins that one bin to the next may skip multiple bars. Instead, we start from the output space we know must be dense and consistently sampled, the bars, and work backwards to figure out what bins we need. This general pattern is called a pullback; there are multiple impressively unelightening wikipedia articles about it.
Once you have this mental model in place you see it’s a matter of iterating over bars and sampling bins:
for (int b = 0; b < B; b++) {
    float f = bar_to_frequency(float(b) + 0.5f, float(B), f0, f1);

    // simple
    bar[b] = bins[int(frequency_to_bin(f) + 0.5f)];
    // or, better for bass bins
    float bin = frequency_to_bin(f);
    float t = bin - floor(bin);
    bar[b] = lerp(bins[floorf(bin)], bins[ceilf(bin)], t);
    // or, less aliasiing
    float f_from = bar_to_frequency(float(b), float(N), f0, f1);
    float f_to = bar_to_frequency(float(b) + 1.0f, float(N), f0, f1);
    bar[b] = average(bins, frequency_to_bin(f_from), frequency_to_bin(f_to));
}
When I write this kind of code I tend to go on auto-pilot so the stuff on this page uses a gaussian window to weight the average and caps the number of bins that can contribute up at high frequencies. This… is not a big deal though.
But now we have too many bass bins. You can say this is wrong pyschoacoustically and go looking at mels or whatever, but it’s also easy to just stitch together two ranges, like
if (b < cutoff) {
    return bar_to_frequency(b, cutoff, f0, f1);
} else {
    return bar_to_frequency(b - cutoff, N - cutoff, f1, f2);
}
So that’s what I do here. I prefer this approach over psychoacoustics because it’s nice to keep everything locally logarithmic: a breakpoint where the logarithmic rate doubles, say, so the same bin count now cover two octaves, looks better to me.
We’re still missing some resolution we’d like to have in the bass and mids, but dealing with that is more than I want to get into for this post.
Problem: linear in magnitude
There is some conspiracy perpetrated by the technically minded that you want decibels for this. Can’t say that I agree. The dynamic range of linear is huge so peaking vocals can look a little preposterous but you can actually see the dynamics you are hearing. Under decibels, pretty much all music looks like a variation on 1/f noise. So my mindset here is we’re trying to compress the dynamic range without squashing it all down as aggressively as a straight log does.
One way to do this is to just ease off on the log by choosing where on the log curve we assign the zero point, computing instead . Then is just a parameter you can scrub until you find something you like. For in , every value of above looks pretty much identical to linear after scaling, so all the interesting stuff is with very small .
This was pretty easy, right? Well, I have more to say. If you just scrub it’s really, really annoying to get control over the dynamic range and keep all the bars sized right. It’s impossible to meaningfully compare different values of if the scale of every bar changes dramatically. If you’ve never dealt with this you may not be in the target audience for this post!
When is in we have that is in . So to get the range back into something sensible we ought to be able to just map the range back linearly:
float compress(float v, float c_param) {
    // Parameterizing c this way is nice for sliders over [0,1]
    float c = powf(2.0f, lerp(-16.0f, 16.0f, c_param));
    return remap(logf(c), logf(c + 1.0f), 0.0f, 1.0f, logf(c + v));
}
This doesn’t work. Firstly, it doesn’t work in the obvious sense that if gives a log scale and gives a linear scale, then we are back where we started, just with numbers in . But the non-obvious sense is that after this map linear magnitudes rarely use values near , and logarthmic rarely uses values near , so we want to boost the gain on linear magnitudes and duck it on logarithmic magnitudes, and it’s not clear how to choose an appropriate gain given an arbitrary .
Easy thing to do here is to stop caring about the entire range and scale with respect to a value we know we’re likely to see in practice, which means tweaking that term. Here I take the range for to be instead. This then boosts the log scale more than we might like so I just apply a fudge factor to bring it back down.
float compress(float v, float c_param) {
    float c = powf(2.0f, lerp(-16.0f, 16.0f, c_param));
    float fudge_factor = square(lerp(0.25f, 1.0f, c_param));
    return remap(logf(c), logf(c + 0.25f), 0.0f, 1.0f, logf(c + v)) * fudge_factor;
}
On most music I point this at, you can see the overall scale shift when you scrub, but on the whole, the most prominent peaks are roughly the same height for all , even if linear only rarely peaks that high.
You MAY be feeling an urge to expand this out and simplify. For most values of you will actually use this may not ever matter but there is a numerical precision point here I’m dumping in a footnote1.
One last point here is A-weighting. A-weighting models how strongly the human ear responds to different frequenices. You should just apply A-weighting. Mostly A-weighting just brings the bass down to something reasonable. To implement A-weighting, you look it up on wikipedia and copy it. Do A-weighting immediately before compress. A-weighting works fine on linear magnitudes, too. If you want to dial A-weighting in a little, it’s a multiplier, so raise it to a power , and that’s the A-weighting power slider here.
Juice
You should dial in A-weighting a little.
Deep in my bones I know that high frequencies ought to react faster than lower frequencies. The way we’re using the FFT doesn’t give us that but we can fake it by scaling the decay rate by
With A-weighting we can do a nice trick. We can make the entire spectrum bounce along with energy in the bass, and since A-weighting pushes the bass down so harshly you can’t tell that the bass is lifting the entire spectrum up mechanically. You want to be a little subtle with this, so I use as a multiplier to apply to every bar before compression, where and are the average FFT bin magnitudes over the frequency ranges defined by the sliders, and dials down the effect. The mids term is mostly to prevent a lack of energy in the bass from ducking too heavily.
Remap
I’ve deliberately used remap a lot in this post because I think it demystifies mapping from linear to logarithmic scales. When you see type junk, and are usually mysterious constants with a simple remap logic lurking in the background. Knowing that you can frame these domain warps as a remap makes it a lot easier to just, write down remap, plug in the ranges you’re interpolating over on either side, and apply the warp to the input or the output. You barely have to think about it.
At work recently I’ve been dealing a bit with colour spaces. Here’s the ACEScct transfer curve written with remap:
if (x <= x_break) {
    return remap(0.0f, x_break, y_black, y_break, x);
} else {
    return remap(logf(x_break), logf(1.0f), y_break, y_white, logf(x));
}
If you simplify this you get the official form. I like this way a lot better! It’s really obvious how the curve is parameterized and I didn’t know, before, that the choice of base was irrelevant. Now I do. Thanks, remap!
Typescript code for this post can be found here.
-
The unlerp immediately computes So large , and here that’s , immediately pushes you to values that require
log1pto avoid roundoff error. Without getting too much into it, floating point numbers get more precise the closer to you are, but, on the other hand, near you have 24 bits of fixed precision in float32. So if you do simplify, simplify all the way tolog1p. For this post, where large values of are pretty pointless, this is not a big deal, but it’s worth knowing that in float32 the log-to-linear interpolation is not really doing what you want if you use the form provided here. In float64, that the visualizer in this post uses, it’s fine. ↩︎